An Introduction to Hugging Face's FineWeb project
I had the opportunity to talk at Prague Crawl, an event for professionals in web scraping and crawling. It was my first time at an event for scraping, and also my first time spending some days in Prague. I’m very thankful to Apify and Massive for the invitation to speak there.
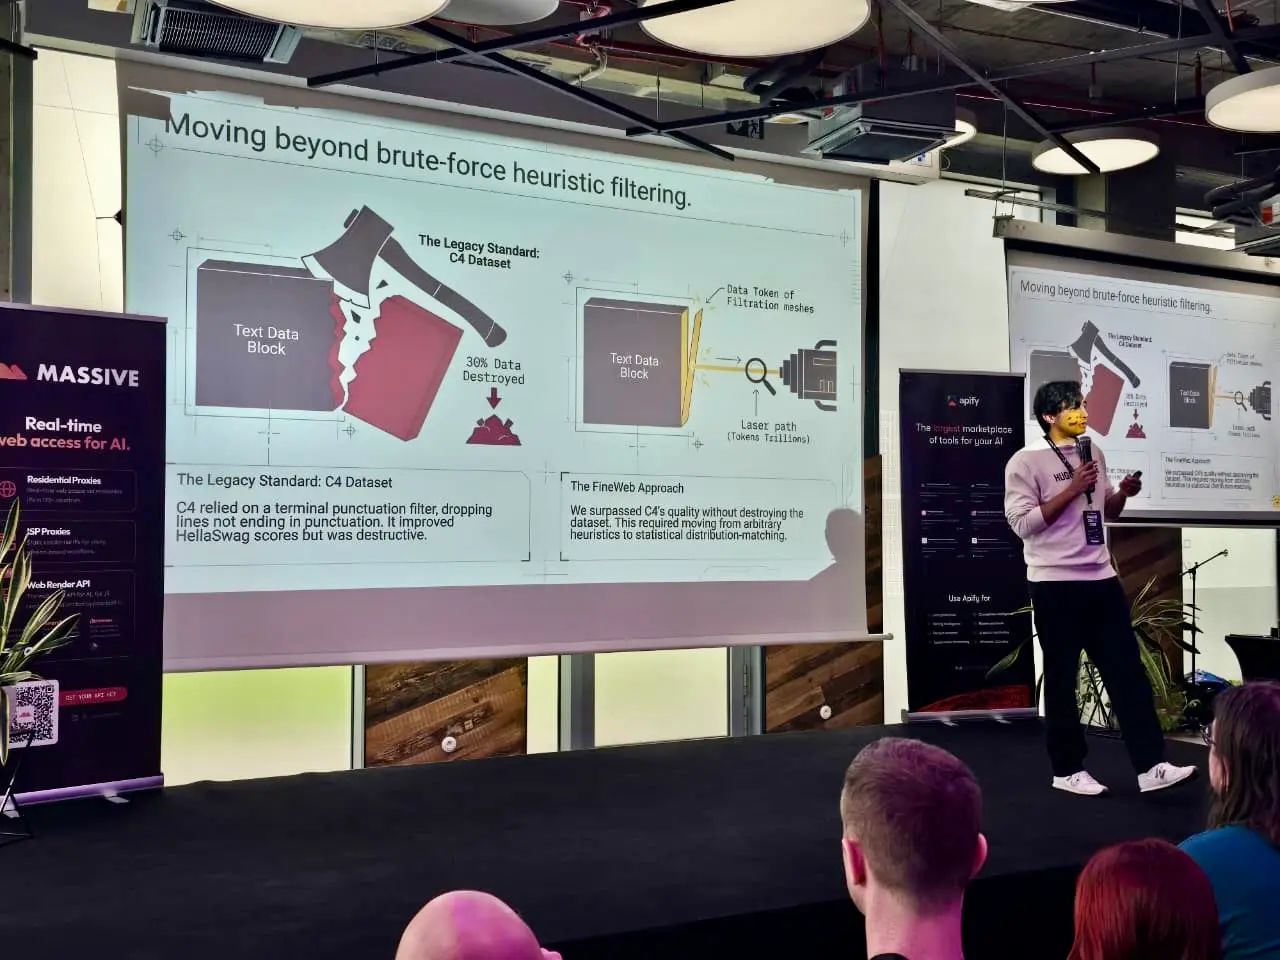
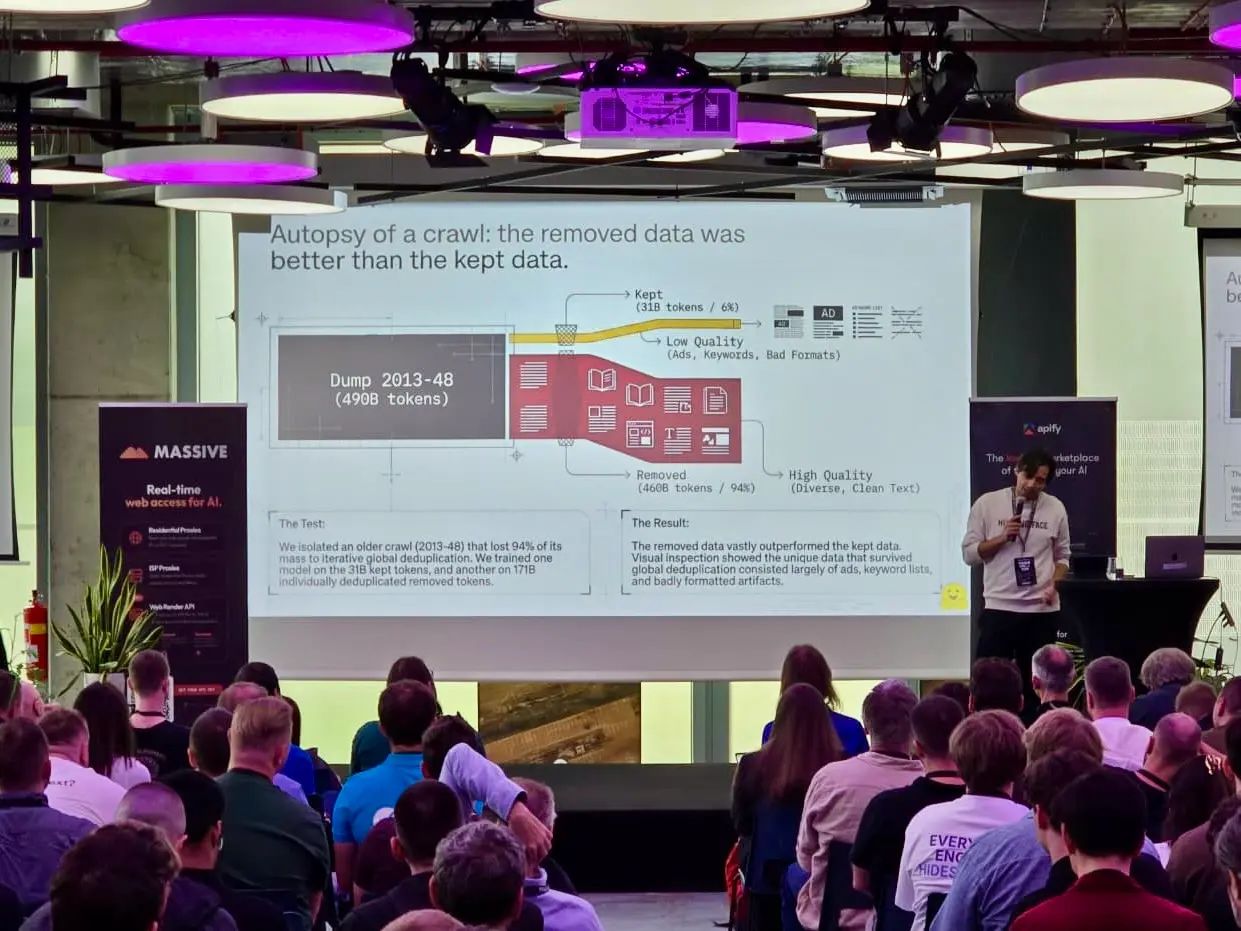
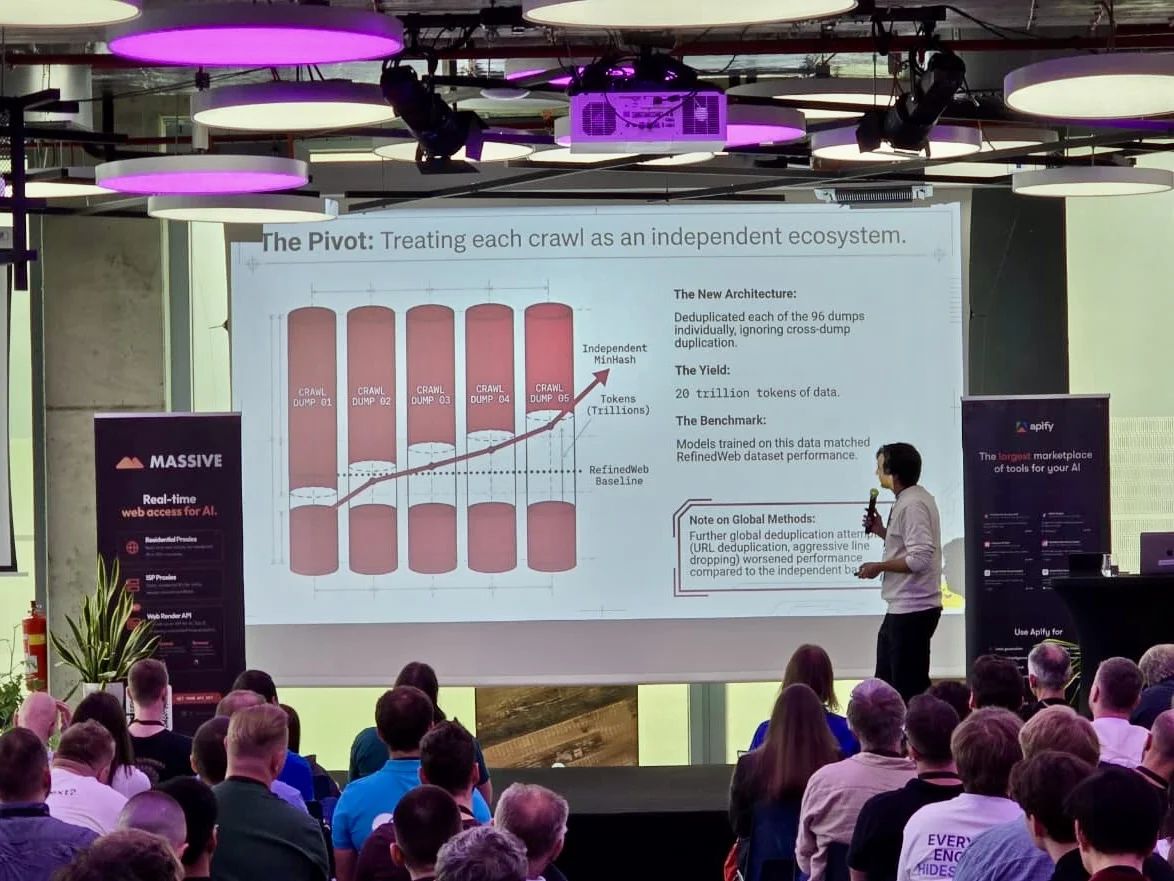
Trying to stay within the field of interest of the audience, I talked about Hugging Face’s FineWeb dataset. I figured that the topic was at least tangential to the occupations of a web crawling professional.
In a nutshell, the aim of the FineWeb project is to democratize the recipe for creating the datasets that train LLMs. Most companies that train LLMs (including open-weight models) do not publish their training material, so finding and creating high-quality datasets is a challenge.
In the talk, I went over how the team cleaned, deduplicated and enhanced the Common Crawl dumps, and the problems that they encountered along the way while creating one of the best performing open datasets for this task. I figured that since this involves dealing with huge datasets of crawled web data, it would be interesting to the audience. As far as I can tell, I was right.
It was a great experience talking to the people behind the modern scraping technologies. I found a very engaged and curious developer community in Prague. Thanks for having me.